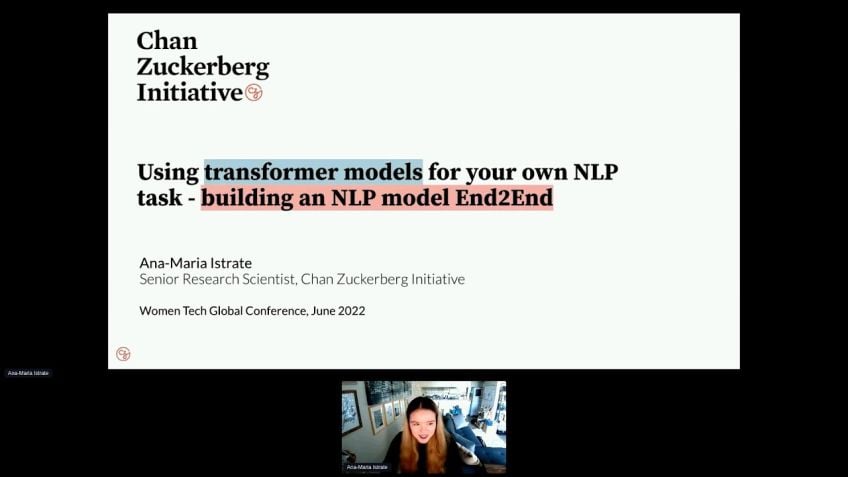
Using transformer models for your own NLP task - building an NLP model End To End
Ana-Maria Istrate17:282022
A 99% F1 score can still hide a model whose output makes no sense
A model can post a 99% F1 score and still produce output that makes no sense to a human reader, and in a niche field like biomedical research that gap decides whether the work is usable. Ana-Maria Istrate, a Research Scientist at the Chan Zuckerberg Initiative, built a transformer model that pulls datasets and experimental methods out of full-text papers. What does getting it right take, from training data to evaluation?
Learn how to define entities, source training data, fine-tune domain models and check real output
Ana-Maria Istrate, Research Scientist at the Chan Zuckerberg Initiative, explains how transformer models work and how to apply them to your own NLP task end to end. Using her team's named entity recognition model for finding datasets and experimental methods in biomedical papers, she covers defining entities, sourcing or curating training data, fine-tuning domain-specific models and pairing metrics with human evaluation.
“One very important thing that I do want to advocate for is human evaluation. So, just sanity checking the output.”
“So the more niche or specialized your domain or task is, the more likely you are to have to create your data set from scratch.”
What you will learn
Explain how self-attention lets transformer models process input all at once, unlike recurrent neural networks.
Write clear entity definitions with domain experts before building a training dataset.
Choose between an openly available dataset and curating your own, based on how specialized the task is.
Fine-tune a pre-trained or domain-specific model such as BioBERT by adding a linear classification layer.
Pair quantitative metrics like precision, recall and F1 with human review of model output.
Key takeaways from the speaker
Building or using an available training corpus for an NLP task
Develop a NLP model for a specific task using state of the art available technology
Evaluating an NLP model
Details
Level
Intermediate
Format
Tech talk
Technical depth
Practitioner
For
Early career, Mid-career, Senior individual contributor
Length
17:28
Published
July 2022
Questions this talk answers
Why did transformer models overtake recurrent neural networks in NLP?
RNNs process input one word at a time, while transformers process it all at once. That allows more parallelization and shorter training times, which led to many large pre-trained models such as BERT and GPT.
Do I need to train a transformer model from scratch for my own task?
No. Through transfer learning you take the weights of a pre-trained model as initialization and fine-tune it, for example by adding a linear classification layer on top that gets trained for your task.
Should I use an open dataset or build my own training data?
The more general the task, the more likely an openly available dataset exists, for example through Hugging Face. The more niche the domain or task, the more likely you need to curate one, which can be time consuming, expensive and need domain knowledge.
What should I do when my domain uses specialized vocabulary?
Use models pre-trained on your specialized domain, such as BioBERT, SciBERT or PubMedBERT for biomedicine, or FinBERT for finance. They share BERT's architecture but are trained on domain corpora and tend to perform better on specialized tasks.
Are high evaluation metrics enough to trust an NLP model?
No. A model can show very high accuracy or F1 and still produce output that does not make sense, so Istrate advocates sanity checking output by hand and getting feedback from domain experts where possible.
About this talk
Transformer models have revolutionized the NLP field and are currently state-of-the art on a variety of tasks, such as named entity recognition, language inference or question answering. With new, more performant models being continuously developed (BERT, RoBERTa, AlBERT, ELECTRA, ERNIE, etc), these models are ubiquitous in virtually all domains that make use of natural language processing.
So how can you apply these models on your own task? In this talk, we will go over the process of using state-of-the-art transformer models for your own NLP task. We will discuss the entire pipeline, from building a training corpus, developing a NLP model and evaluating the model. We will offer an example of building a model to extract mentions of Experimental Methods and Datasets from full-text biomedical papers. Even though our example will focus on an NLP task for the biomedical text, the framework can be applied to any domain.
All right. Hi, everyone, and thank you so much for being here. I'm really excited to talk to you today about Transformer Models for Natural Language Processing and building an NLP model end-to-end. First of all, hi. I am really happy to be here today. My name is Ana-Maria Istrate, or Ana. I am a Senior Research Scientist. at Chan Zuckerberg Initiative. And my interests lie at the intersection of NLP and applications of NLP on the scientific domain, in particular, text mining, biomedical literature, predicting impact of research outputs, knowledge graphs, and graph-based models.
This is the outline of what we will be covering today. So I would like to share with you a little bit of a background, some background information about Transformer Models, in particular, how they relate to Natural Language Processing tasks. And then we will go into the process of building a Transformer-based NLP model end-to-end. We will be talking about the training data set and the importance of having good definitions of what to include in the training data set. We will touch on the options of choosing an openly available data set versus curating one from scratch. We will then move into model development and talk about the transfer learning, the idea of fine-tuning model versus pre-training from scratch. And some of the challenges that come with specialized corpora. We will end with model evaluation and talk about quantitative and qualitative evaluation. For the second part of our talk, we will use an example of building a named entity recognition model to mine different types of entities from biomedical text. But if you're not interested in the biomedical domain or you feel you don't have domain knowledge for the biomedical
domain knowledge for the biomedical field, that's totally fine. That's not very relevant to our talk today and you'll still be able to follow along. Awesome. So with that in mind, I am excited to get started and talk about Transformer models in natural language processing. So Transformer models have become really popular mainly in natural language processing and computer vision. And Transformer models are essentially deep learning models that are based on this idea of self-attention. And self-attention is a concept that basically basically wants to, or helps us understand the representation of a current word given its context in the input sequence.
So for instance, we have this example of a sentence on the slide. The animal didn't cross the street because it was too wide. If we want to compute a representation for the word it, as humans, we might know that the word it refers to the street and not to the animal. However, we need to install this sort of information in machine learning models as well. And this is exactly what self-attention aims to do. Basically, when computing a representation for a particular word, we want to know what other words in the sequence we should attend to. What other words are relevant to our current representation?
Okay. And the notion of self-attention is at the core of the Transformer architecture. And the Transformer architecture has firstly been introduced in 2017. Once introduced, Transformer-based natural language processing models pretty much became state-of-the-art in natural language processing. And before that, the state-of-the-art in NLP tasks were recurrent neural networks or RNNs. The difference between RNNs and transformer models is that in RNNs, the input gets processed sequentially. So one word at a time. However, in transformer architectures, we are able to process the input all at once.
This means that transformers allow for more parallelization than recurrent neural networks. And it also means that we get reduced training times. So as an example of how this happens, for instance, we have this diagram of a recurrent neural network at the bottom. When we're feeding input in a recurrent neural network, we're basically reading the input one word at a time.
Because transformer models don't need to follow this sort of like pattern, it means that we get reduced training times. And this led to the development of a really large number of models of pre-trained language models based on the transformer architecture. So maybe you've heard of things such as BERT, which stands for bi-directional encoder presentations from transformers, GPT, which stands for generative pre-trained transformers, T5, Roberta, Electra, Albert, Ernie, and the list can go on and on and on.
There are a lot of really high-performing models based on the transformer architecture. And the reason why, you know, the reason why these models perform really well on a variety of tasks such as named entity recognition, question answering, summarization, or machine learning translation is because these models are being pre-trained on huge amounts of text. So they learn to capture complexities in natural language from the training corpus really well.
However, the really cool thing is that you don't have, if you want to use one of these models, you don't have to train them from scratch every time you want to, you want to do that. You can use them by fine tuning them on your own particular task. And this is behind this concept of transfer learning. So fine tuning means that you're basically taking the weight of a model that has been pre-trained, already pre-trained.
And you can use these weights as initialization for a new model. For instance, we have the BERT model, which has been pre-trained on the books corpus and English Wikipedia data sets. And we can take this model architecture and finding it on our own particular tasks, whether this is named entity recognition, question answering, or sentence classification. All right, so hopefully that gave us a little bit of an, of an understanding of transformer models and how they are being used in natural language processing.
The next thing I want to go over is building a transformer based model, a transformer based NLP model end to end. As mentioned, we will be talking about the training data set, model development and model evaluation. And for this part of the talk, we will focus on an example of building a named entity recognition model that mines different types of entities from biomedical text.
And we build this model at Chan Zuckerberg initiative. Our task with this model was to extract mentions of data sets and experimental methods from biomedical research articles. So essentially, if we have a piece of text that happens to be coming from a biomedical research article, and we have an example of this paragraph on this slide. Our task here is to be able to extract data sets and experimental methods from this piece of text.
Data sets can look like identifiers in a database or repository. So basically these GSE mentions that we see here on the slide. And experimental methods can look at this method that's being found in this paragraph, ChIP-seq, which is the sequencing method. How we end up extracting these mentions of data sets and experimental methods from biomedical research articles is through a named entity recognition model that basically learns to recognize these entity types from text.
And if you're not familiar with the named entity recognition task, named entity recognition aims to locate and classify named entities in unstructured text into predefined categories. So in our case, our predefined categories are data sets and experimental methods. And we want to be able to locate and classify all of the named entities in this piece of text that fall into either one of these two categories.
So the first thing I wanted to talk about in this process is building the training data set. And the first step we took in building our training data set is we asked ourselves what gets included. And I do want to emphasize the importance of having entity definitions. For us, it was very important to know what exactly do we mean by data sets and experimental methods.
What exactly gets included into each of these predefined categories. And definitions are particularly important, especially for specialized domains or tasks or boundaries are not very clear. So for us, you know, we want to be able to identify experimental methods, but it wasn't very clear if we should include things like software, equipment, regions, or other types of entities.
And luckily we do have a team of biomedical experts at CZI that we can collaborate with and that can give us domain expertise. So we collaborated with them to come up with these definitions. Once we have, once we have good definitions for what we want to include in our data set, the actual, the next step is actually creating the data set.
And this, and here we usually have two main options. One, we can use an openly available data set. And there are lots of data sets that are openly available. There are even, there are more than 5,000 data sets available only through the Hugging Face API. And these are easy to load and use with just a few lines of code.
And the more general your task is, the more likely it is that you will be able to find an openly available data set for your particular task. The other option is to create a data set from scratch. So the more niche or specialized your domain or task is, the more likely you are to have to create your data set from scratch.
In our case, we not only dealt with a specialized domain like the biomedical field, but we also have a very specialized task of being able to identify particular mentions of data sets and experimental methods. Creating a data set from scratch comes with its own set of challenges. And it usually involves some type of curation. You know, maybe you have product or user data and you want to be able to build a model that learns from this.
Maybe you have things like user logs or user interaction data, which is likely to be very noisy. And it is very likely you'll have to clean up this data in order to be able to build a high quality training data set for a machine learning model. Or maybe you don't have product or user data and you just want to build your data set from scratch.
In our case, we do have this by a creation team that I mentioned that we can use in order to create these data sets from scratch if we want to. If you don't have access to that type of resource, there are other types of resources such as Mechanical Turk or, you know, that uses crowd sourcing. And there are also curation companies who specialize in building high quality training data sets.
And some of them have also specialized expertise. We've been using some of them for the biomedical field as well. Creating a data set from scratch, again, comes with its own set of challenges because it is time consuming, could be expensive, and it might involve specialized domain knowledge. In our case, we use the combination of both where we use openly available annotations.
There is a platform for the biomedical field. It's called Europe PMC. This platform provides openly available annotations from biomedical research articles. However, their annotations did not exactly fit our own definitions. So, we took this openly available data and we further curated it with the help of our bio creation team. For us, that meant excluding terms that did not fit our own definitions.
Cool. So, we've talked about the training data set. We've talked about the importance of having good definitions, about the options of using an openly available data set. Versus curating one from scratch. The next part of our talk today will focus on model development. So, going back to this notion of transformer models and transfer learning, where you can use one of these pre-trained language models on your own particular task by fine-tuning them without having to train from scratch.
We define fine-tuning again as taking the weights of a trained model and using them as initialization for a new model. How does this look like in practice? So, in practice, we took a pre-trained model such as BERT. This is kind of like the blue module that you see on this diagram. We initialize the model architecture from a pre-trained language model with the frozen weights from this particular model.
And then we add a linear classification layer on top. And this is essentially the fine-tuning part. This is what gets trained. In our case, the linear classification layer was in charge of basically classifying each of the tokens as being part of either a method or a data set. I do want to talk a little bit about specialized domains and mention the fact that specialized domains have different word distributions than general domains.
And specialized domains, that's because specialized domains usually contain specialized terms. So, for the biomedical field, these could be genes, cell lines, or diseases. And there are other specialized terms such as finance or law that have the same types of challenges. The idea here is that representations learned by models from general domain text might not be able to capture all of these complexities for specialized domains.
The solution then is to use models that are pre-trained on your own specialized domain. Because these tend to give better performance on your specialized task. So, for the biomedical field, we have models such as BioBERT, SciBERT, and PubMedBERT. And these are essentially models that have the same model architecture as BERT. The only difference between them and BERT is the corpora they have been trained on.
So, some of these models have been trained on biomedical research articles or scientific articles. And there are similar models for other types of domains such as FinBERT for the financial field, LawBERT for law, and I'm sure there's other for other types of domains. Cool. So, we went over the training dataset, talk about definitions using an openly available dataset versus curating from scratch.
We touched on model development and the idea of transfer learning, fine-tuning versus pre-training a model. And some of the challenges of specialized corpora. The last thing I want to talk about is model evaluation. And talk about quantitative versus qualitative evaluation. So, the first thing that you do when evaluating a machine learning model is you'd look at quantitative measures such as precision, recall, F1 score, accuracy, blue score.
Whatever your task is, there's usually some widely accepted metric, quantitative metric, that you can use to evaluate your machine learning model. One very important thing that I do want to advocate for is human evaluation. So, just sanity checking the output. More often than not, you can get really high metrics such as, you know, 95% accuracy, 99% F1 score.
And when actually looking at the output of the model, it doesn't make sense. Or maybe, you know, it's not exactly what we would expect. So, without sanity checking the output, we would not be able to, like, catch that and go back and fix it. And you don't really have the main expertise for that. You don't really need to have the main expertise for that.
However, sometimes the main expertise, it is helpful to have. So, for us, again, we have this team of biomedical curators that we are able to consult at different stages in model development. So, more often than not, we take output of some of our trained machine learning models and we put it in front of them. And they are able to tell us or, like, to give us feedback on where is the model failing?
What is the model not picking up? Where could the model be improved? This feedback is very valuable for us because we can then go back and incorporate it into the model development. So, this is all I wanted to share with you today as a recap of what we went over. We talked about transformer models for natural language processing.
We then talked about the process of building a transformer-based NLP model end-to-end. We talked about the training dataset and the importance of having good definitions and what to include and what not to include. We talked about using an openly available dataset or curating one from scratch. And then we touched on model development and talked about transfer learning, the idea of fine-tuning versus free training on a model, and some of the challenges of specialized corpora.
We ended by looking at model evaluation and talked about quantitative versus qualitative evaluation. Thank you so much for listening. If you want to check us out, please check out the Chan Zuckerberg Initiative or CCI handles and also check out the Science Initiative within CCI. Thank you so much for being here. I hope you have a great rest of the conference and great rest of the day.
Thank you.
Transcribed automatically; names checked against the speaker record. Select a time to jump there.
Article based on this talk
What it takes to adapt a transformer model to a specialized NLP task
Ana-Maria Istrate walks through the full pipeline, from entity definitions and training data to fine-tuning and human evaluation, using a biomedical case study.
In short
You rarely need to train a transformer model from scratch: you fine-tune a pre-trained one, ideally one trained on your own domain. Ana-Maria Istrate, Research Scientist at the Chan Zuckerberg Initiative, argues that the hard parts sit on either side of the model: defining exactly what you want to extract, building training data that matches those definitions, and checking the output with human eyes rather than trusting metrics alone.
Key takeaways
Build or use an available training corpus for an NLP task.
Develop an NLP model for a specific task using state-of-the-art available technology.
Evaluate an NLP model.
Why transformers changed natural language processing
Istrate opens with the idea at the heart of the transformer architecture: self-attention. Using the sentence "The animal didn't cross the street because it was too wide", she shows that a model needs to learn that "it" refers to the street, not the animal. Self-attention is how it does that.
"Basically, when computing a representation for a particular word, we want to know what other words in the sequence we should attend to." (2:41)
As the speaker explained, the architecture was introduced in 2017 and quickly became state of the art, replacing recurrent neural networks. Where RNNs read input one word at a time, transformers process it all at once, which allows more parallelization and shorter training times. That shift led to a long list of pre-trained language models, including BERT, GPT, T5, RoBERTa, ELECTRA, ALBERT and ERNIE, which perform well because they are pre-trained on huge amounts of text.
The practical consequence is transfer learning. Rather than training these models yourself, you take the pre-trained weights and use them as the starting point for a new model.
"You can use them by fine tuning them on your own particular task. And this is behind this concept of transfer learning." (5:22)
Start with definitions, then find or build the data
The case study is a named entity recognition model Istrate's team built at the Chan Zuckerberg Initiative to extract mentions of datasets (such as GSE identifiers) and experimental methods (such as ChIP-seq) from biomedical research articles. Before touching data, the team asked what should be included in each category. Should software, equipment or other entities count as experimental methods? They worked with the organization's biomedical experts to settle it.
"And definitions are particularly important, especially for specialized domains or tasks or boundaries are not very clear." (8:33)
With definitions in place, there are two routes. Openly available datasets are plentiful; as the speaker cited, more than 5,000 are available through the Hugging Face API alone, and they load with a few lines of code. But the more specialized the work, the less likely an off-the-shelf set will fit.
"So the more niche or specialized your domain or task is, the more likely you are to have to create your data set from scratch." (9:39)
Creating data from scratch usually means curation: cleaning noisy product or user data, or annotating from nothing using an in-house team, crowdsourcing such as Mechanical Turk, or specialist curation companies. Istrate is candid that this is time consuming, can be expensive and may need domain knowledge. Her team combined both routes: they started from openly available annotations on Europe PMC, then had their biocuration team remove terms that did not fit their own definitions.
Fine-tune, and choose a model that speaks your domain
In practice, the team initialized the architecture from a pre-trained model such as BERT with frozen weights, then added a linear classification layer on top. That layer is what gets trained; in their case it labels each token as part of a method or a dataset.
Istrate then turns to a trap for anyone working outside general text. Specialized fields such as biomedicine, finance and law have different word distributions, full of terms like genes, cell lines or diseases, and representations learned from general text may miss them.
"The solution then is to use models that are pre-trained on your own specialized domain." (13:46)
For biomedicine she points to BioBERT, SciBERT and PubMedBERT, which share BERT's architecture but were trained on scientific or biomedical articles. She also mentions FinBERT for finance and LawBERT for law.
Metrics are not the end of evaluation
The final stage starts with the familiar quantitative measures: precision, recall, F1, accuracy or BLEU, depending on the task. Istrate's strongest advice is what comes next.
"One very important thing that I do want to advocate for is human evaluation. So, just sanity checking the output." (15:03)
She warns that a model can show very high numbers, such as 95% accuracy or a 99% F1 score, yet produce output that does not make sense when someone reads it. Basic sanity checks need no special expertise, but domain experts add a lot. Her team regularly puts model output in front of its biomedical curators, who point out where the model fails, what it misses and where it could improve.
"This feedback is very valuable for us because we can then go back and incorporate it into the model development." (16:09)
The framework, she stresses, is not tied to biomedicine: the same steps apply to any domain.
Watch the talk
"Using transformer models for your own NLP task - building an NLP model End To End" by Ana-Maria Istrate, 17 minutes: https://www.womentech.net/video/using-transformer-models-your-own-nlp-task-building-nlp-model-end-end-ana-maria-istrate
About the speaker
Ana-Maria Istrate is a Research Scientist at the Chan Zuckerberg Initiative, where she has primarily worked on recommendations, ranking and text mining algorithms that support retrieving knowledge from biomedical journal articles. She holds a Bachelor's degree in Applied Math and a Master's degree in Computer Science (Artificial Intelligence track) from Stanford, and her interests lie at the intersection of natural language processing, text mining and applications that serve the scientific community.
Questions this talk answers
Why did transformer models overtake recurrent neural networks in NLP?
Do I need to train a transformer model from scratch for my own task?
Should I use an open dataset or build my own training data?
What should I do when my domain uses specialized vocabulary?
Are high evaluation metrics enough to trust an NLP model?
Drafted with AI from the talk transcript. Editor review pending.
Frameworks and ideas mentioned
Transformer architecture
Self-attention
Transfer learning
Named entity recognition
Recurrent neural networks
Resources mentioned
Hugging Face datasets (Hugging Face API)
Europe PMC
Amazon Mechanical Turk
BioBERT
SciBERT
PubMedBERT
FinBERT
LawBERT
Cite this talk
Ana-Maria Istrate. "Using transformer models for your own NLP task - building an NLP model End To End." WomenTech Network, 2022. https://www.womentech.net/video/using-transformer-models-your-own-nlp-task-building-nlp-model-end-end-ana-maria-istrate